What screening hands your analysts
A common name returns forty hits
Each one a possible match until someone proves otherwise.
Minutes per alert, spent proving a negative
Open the article, check the age, the country, the date. Write it down. Next.
Two analysts, two dispositions
The same hit gets a different call depending on who picks up the case.
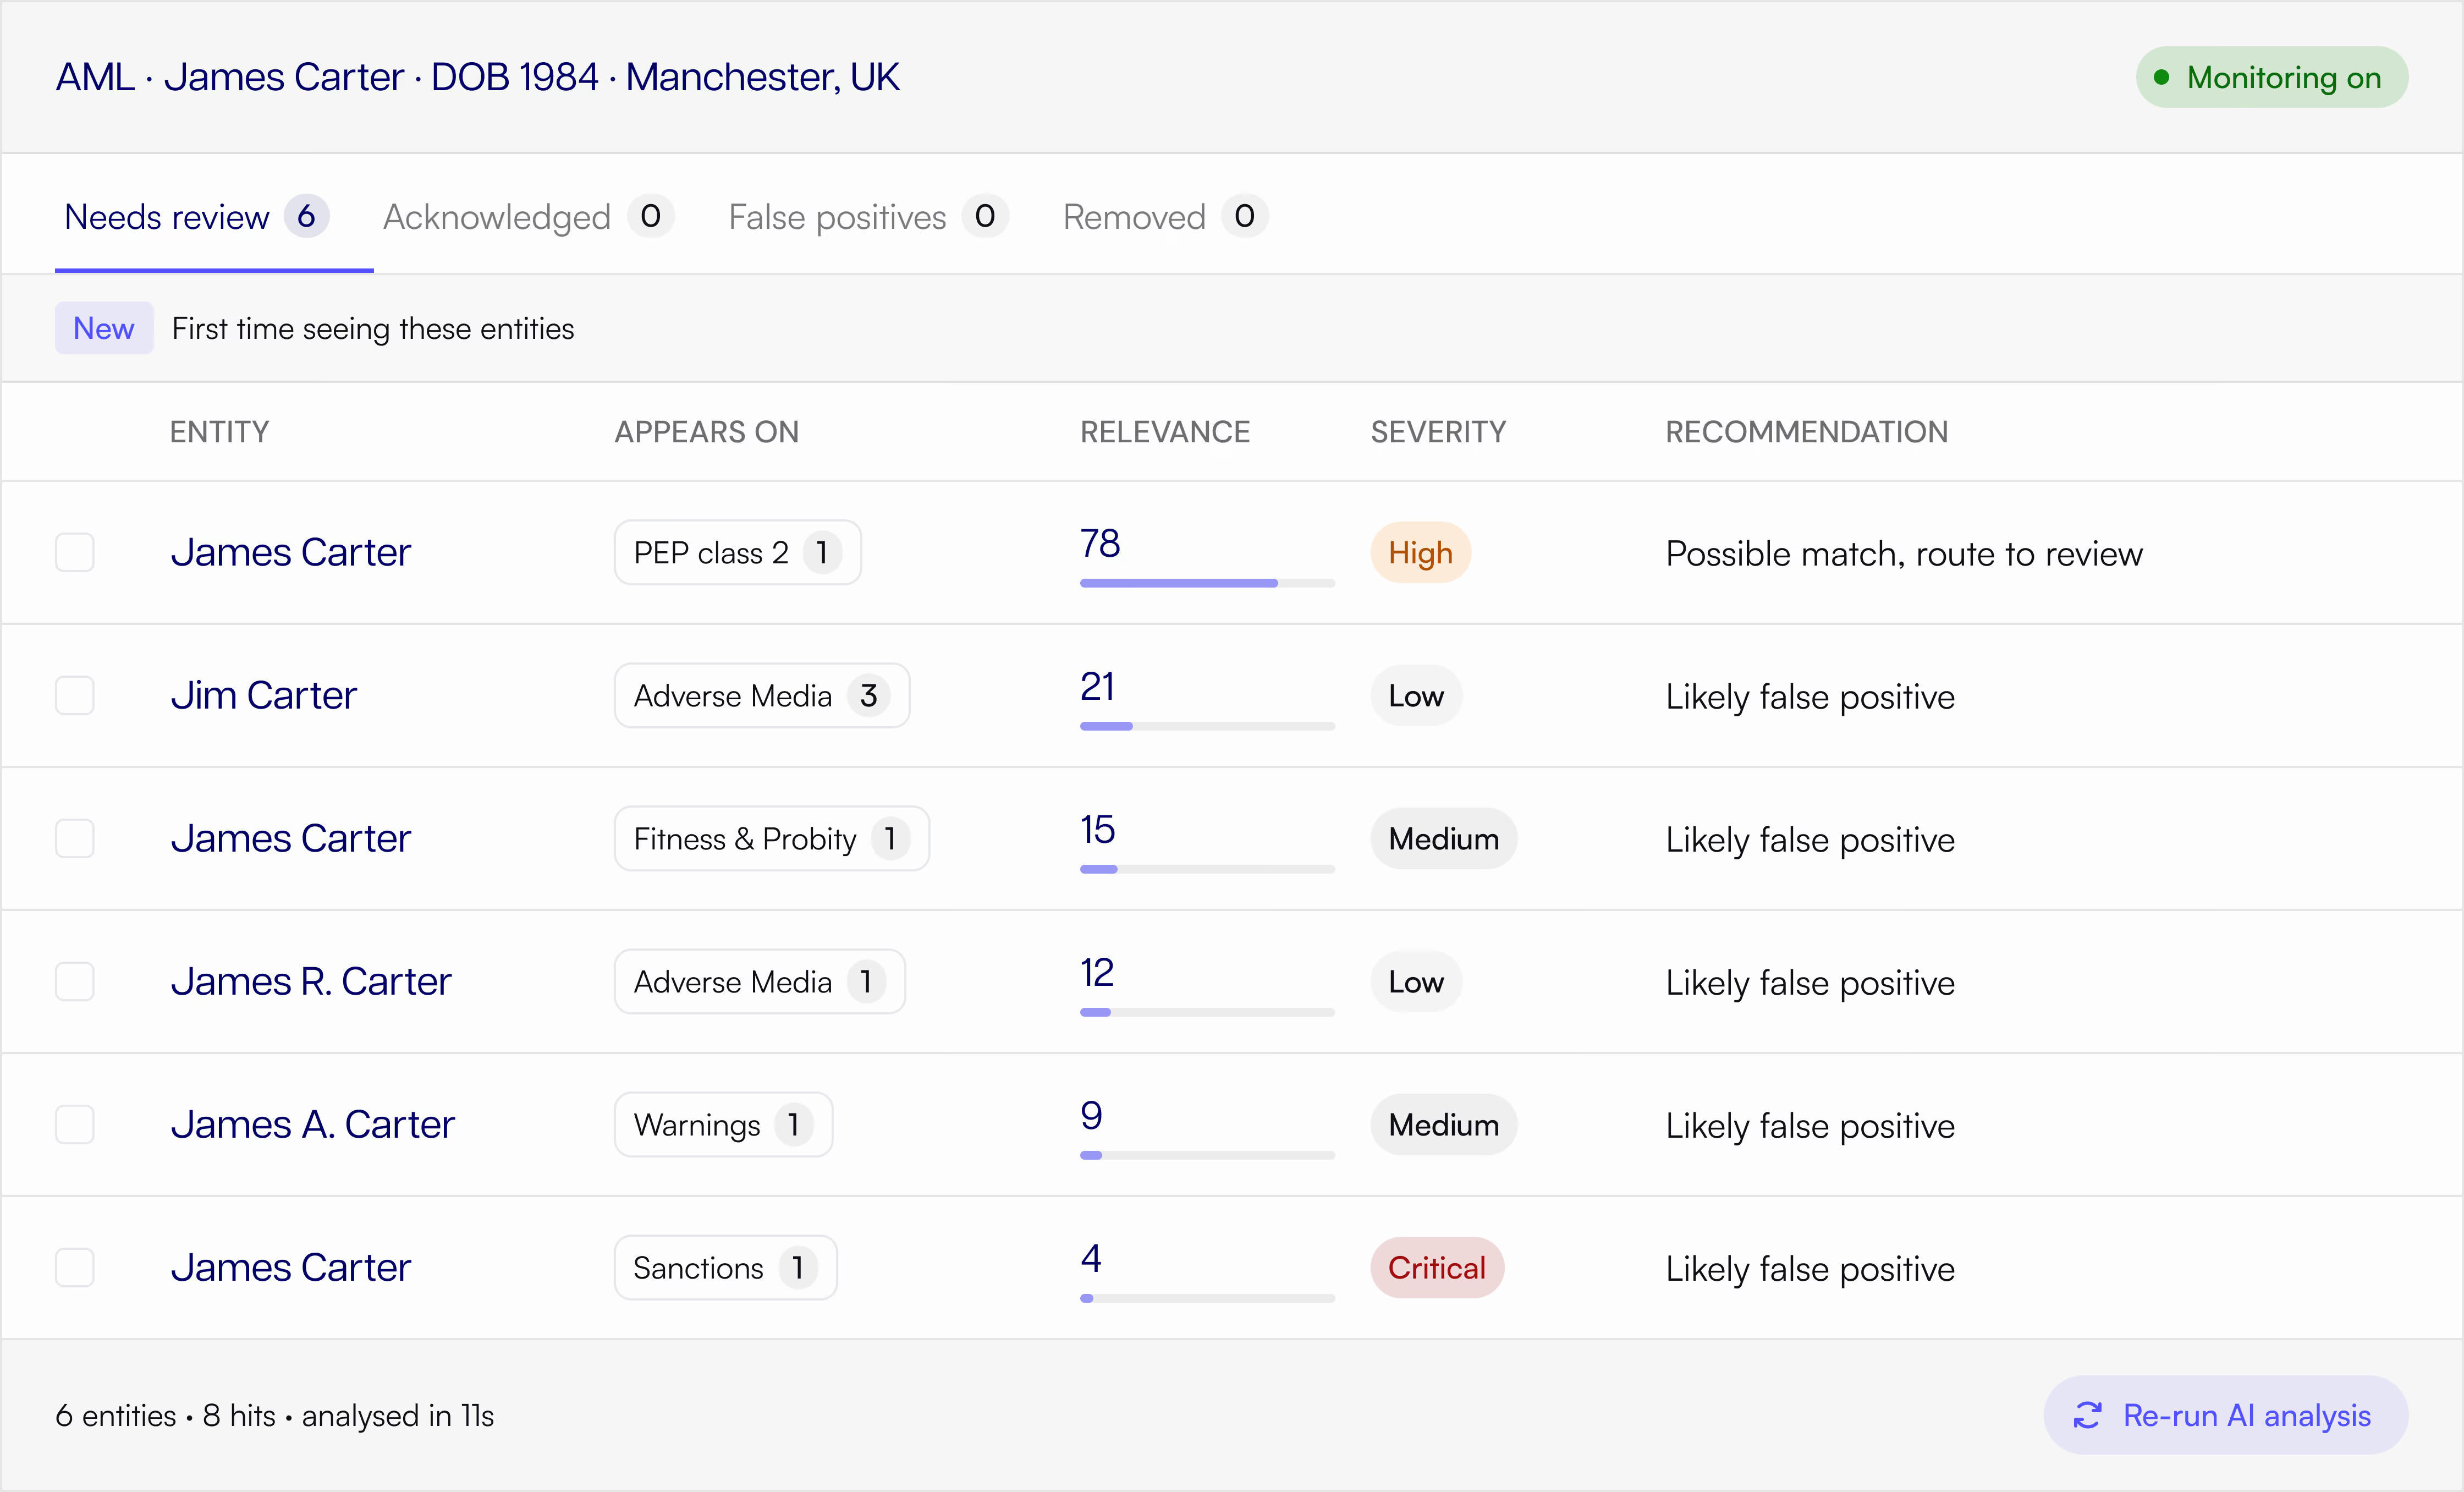
Every hit, every type,scored and explained
Sanctions, PEP, warnings, fitness and probity, adverse media in any language. The agent reads each hit, scores identity match and seriousness, and recommends a disposition under your policy.
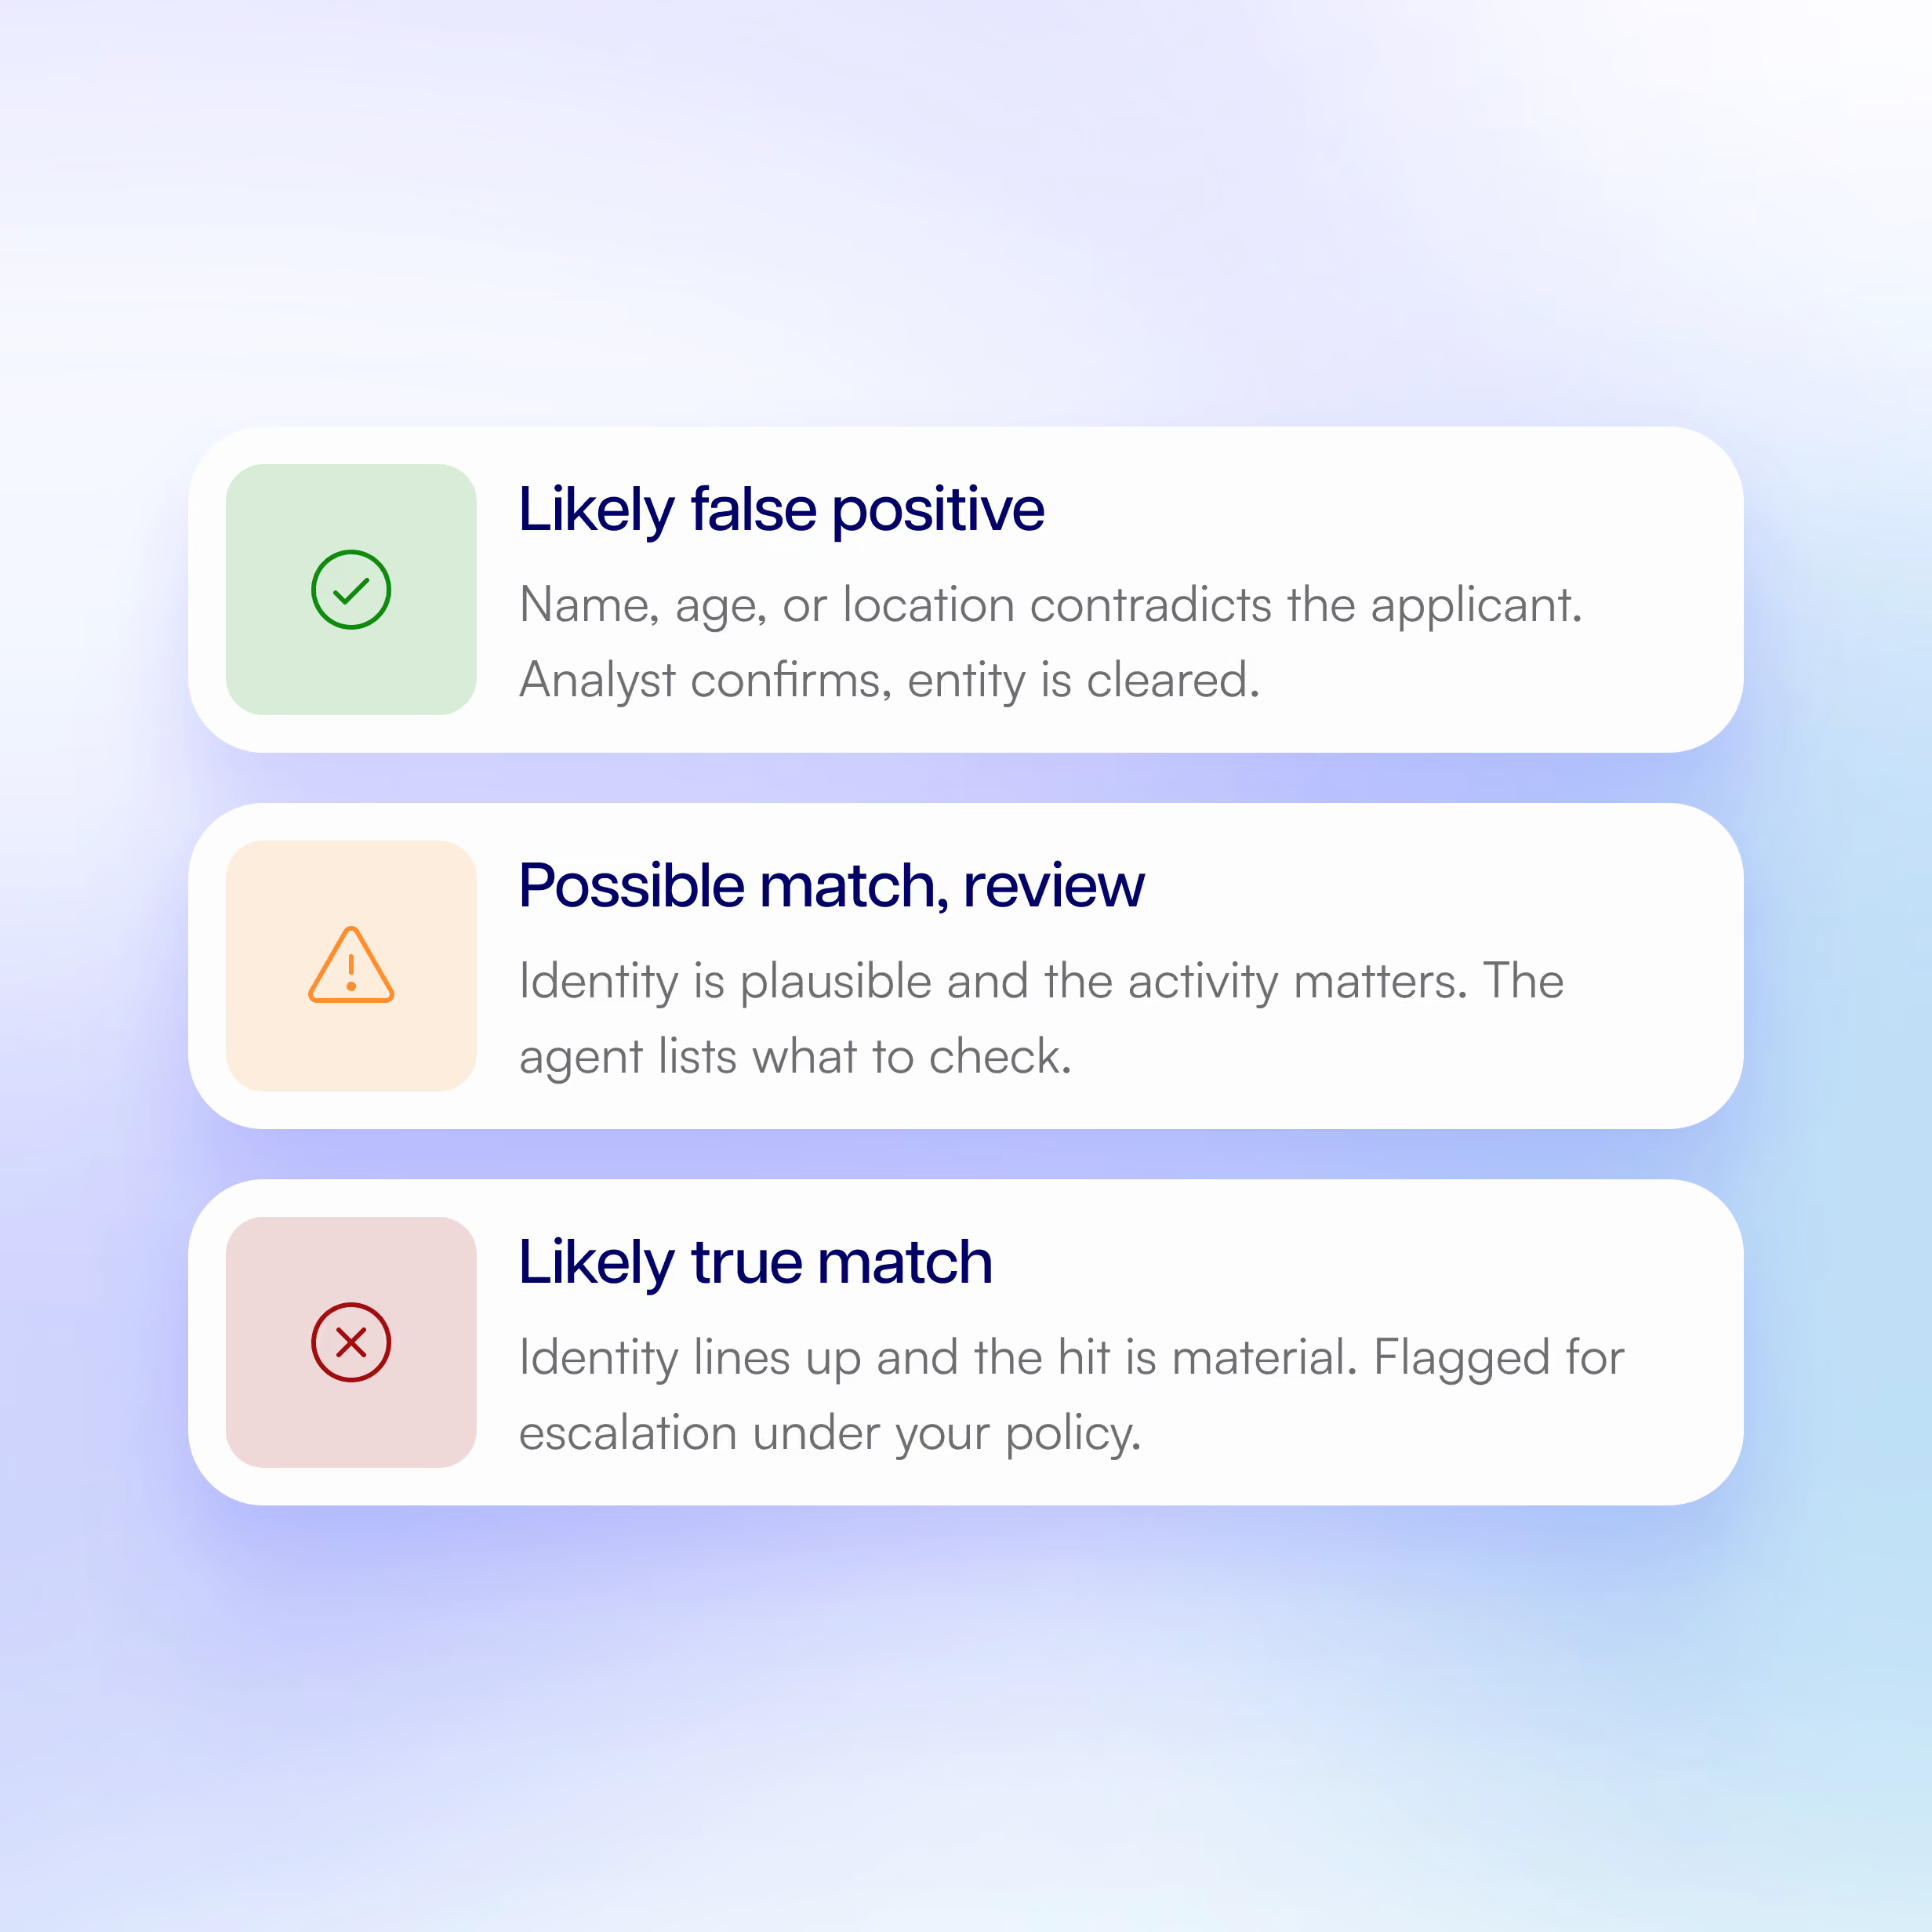
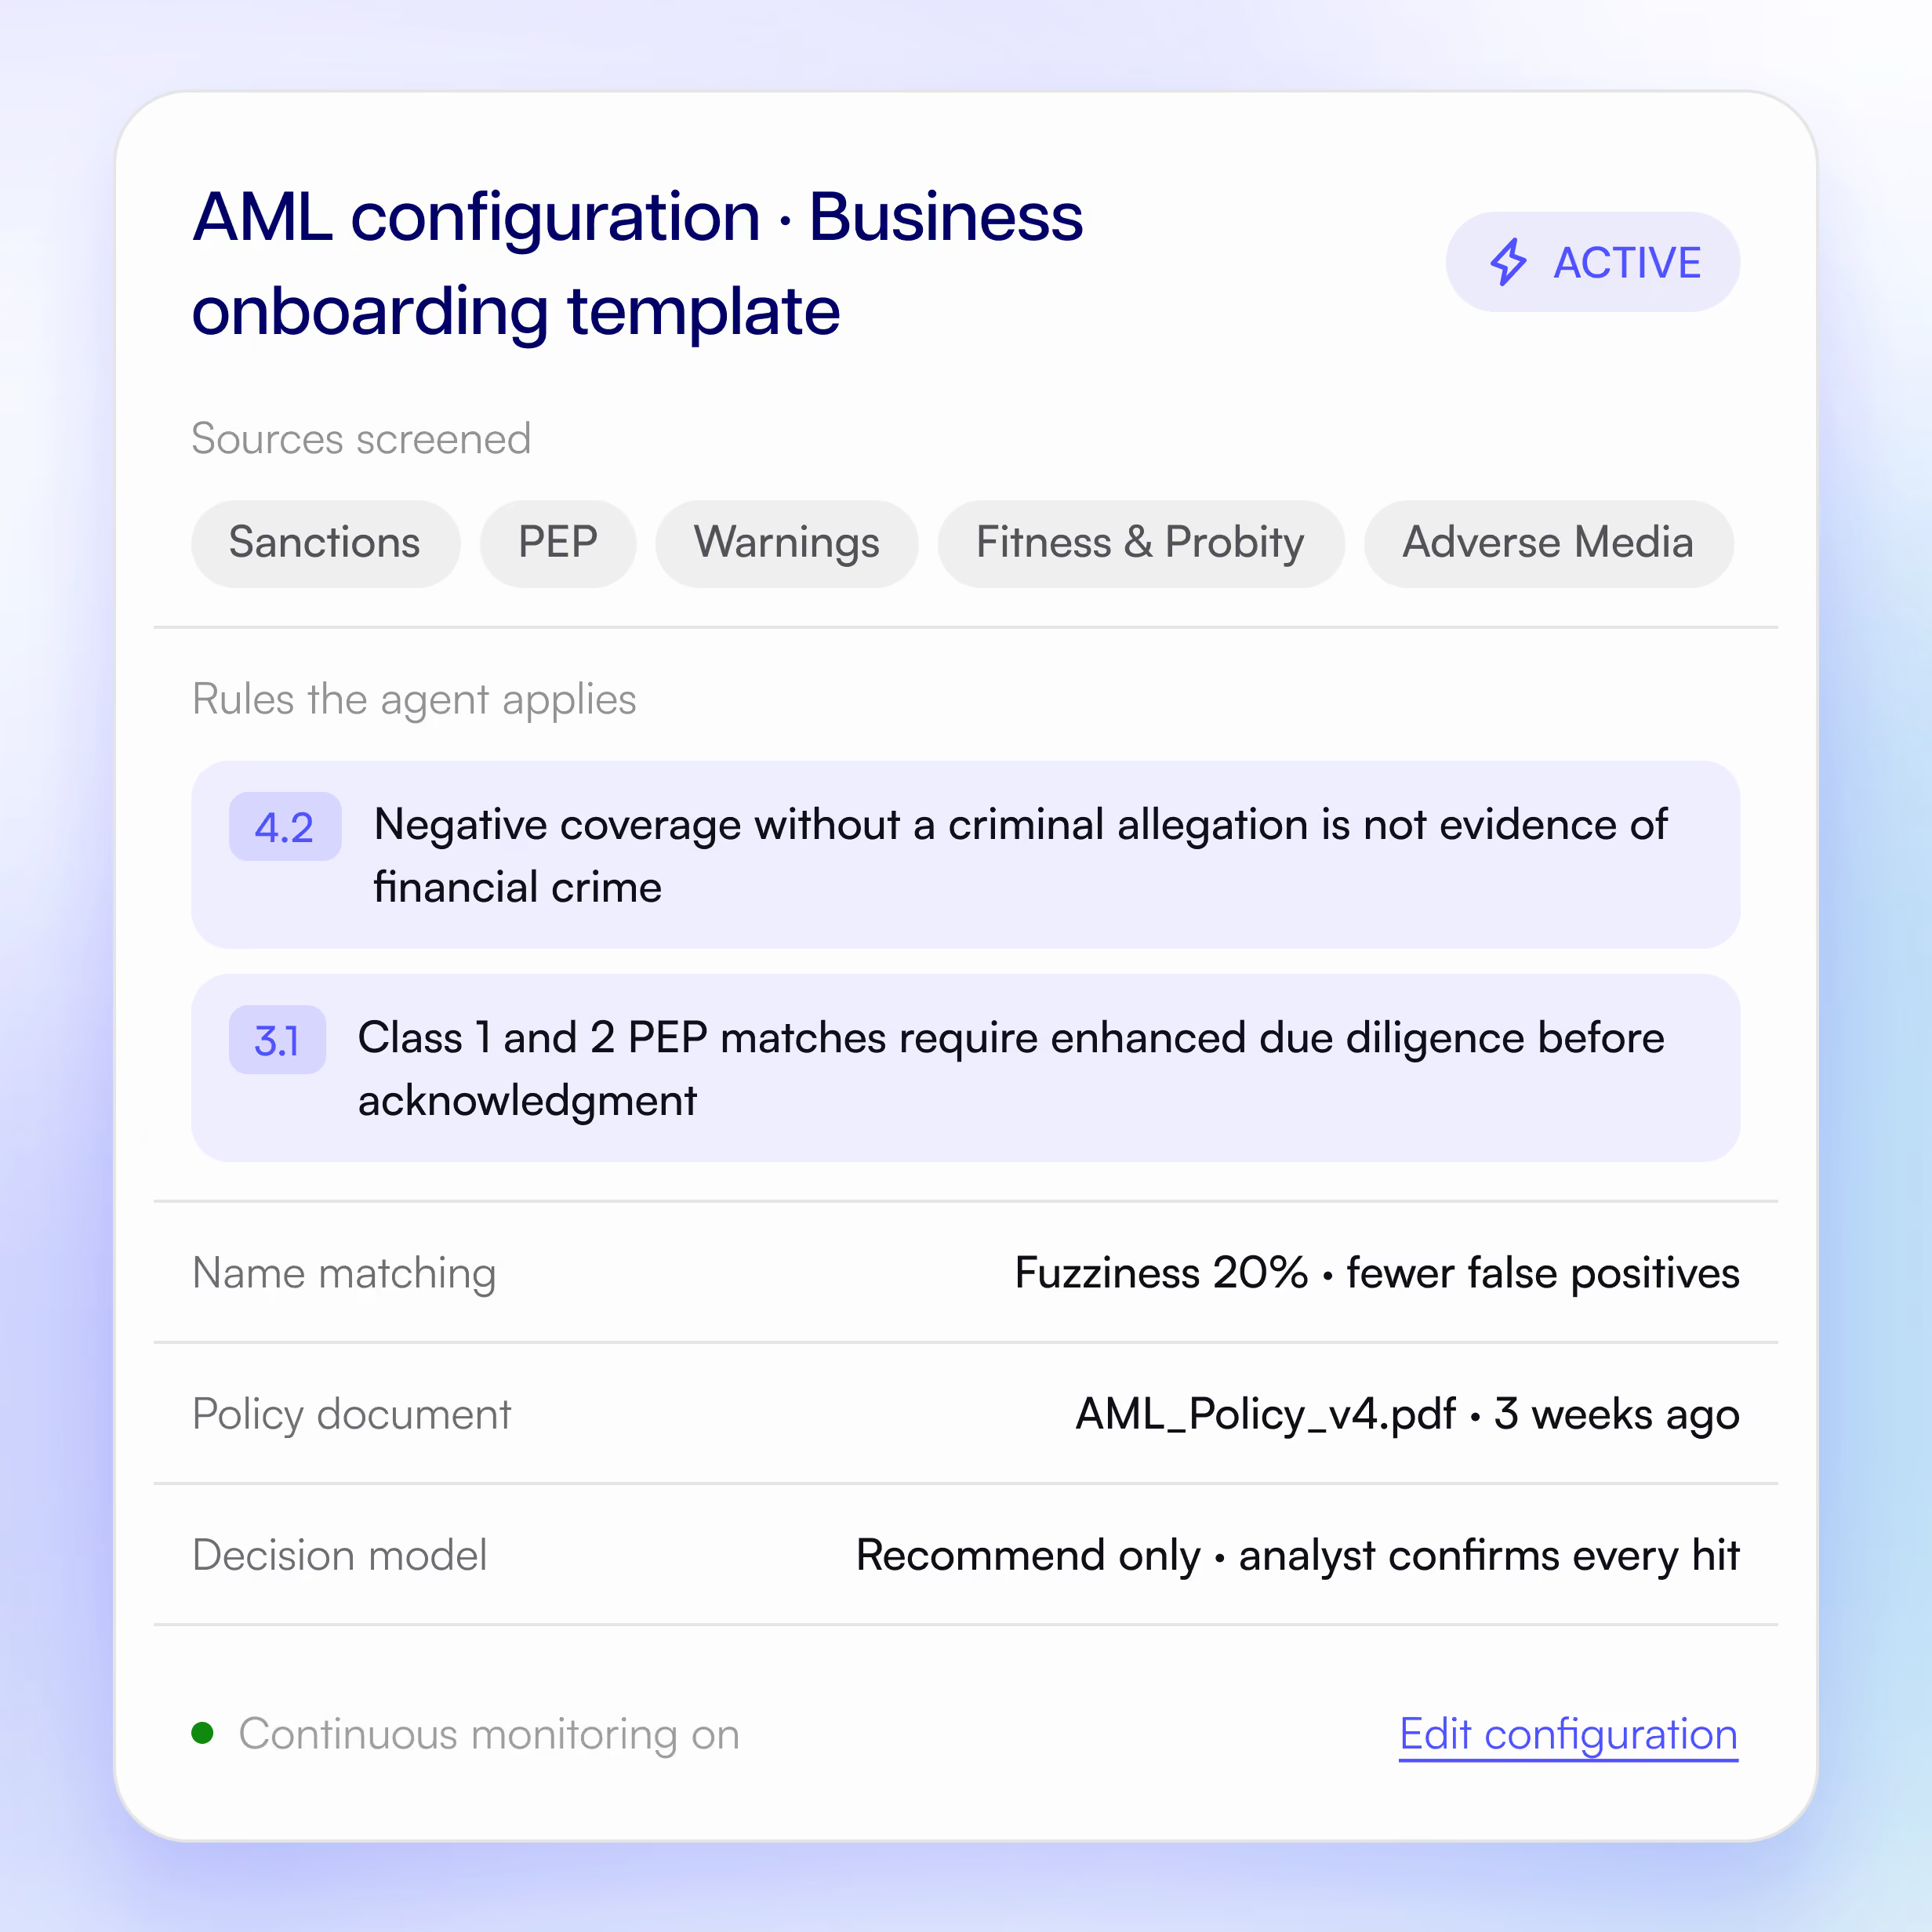
The agent recommends. Your analyst decides
Three possible recommendations, each with a written rationale. Nothing is cleared or declined until an analyst says so.
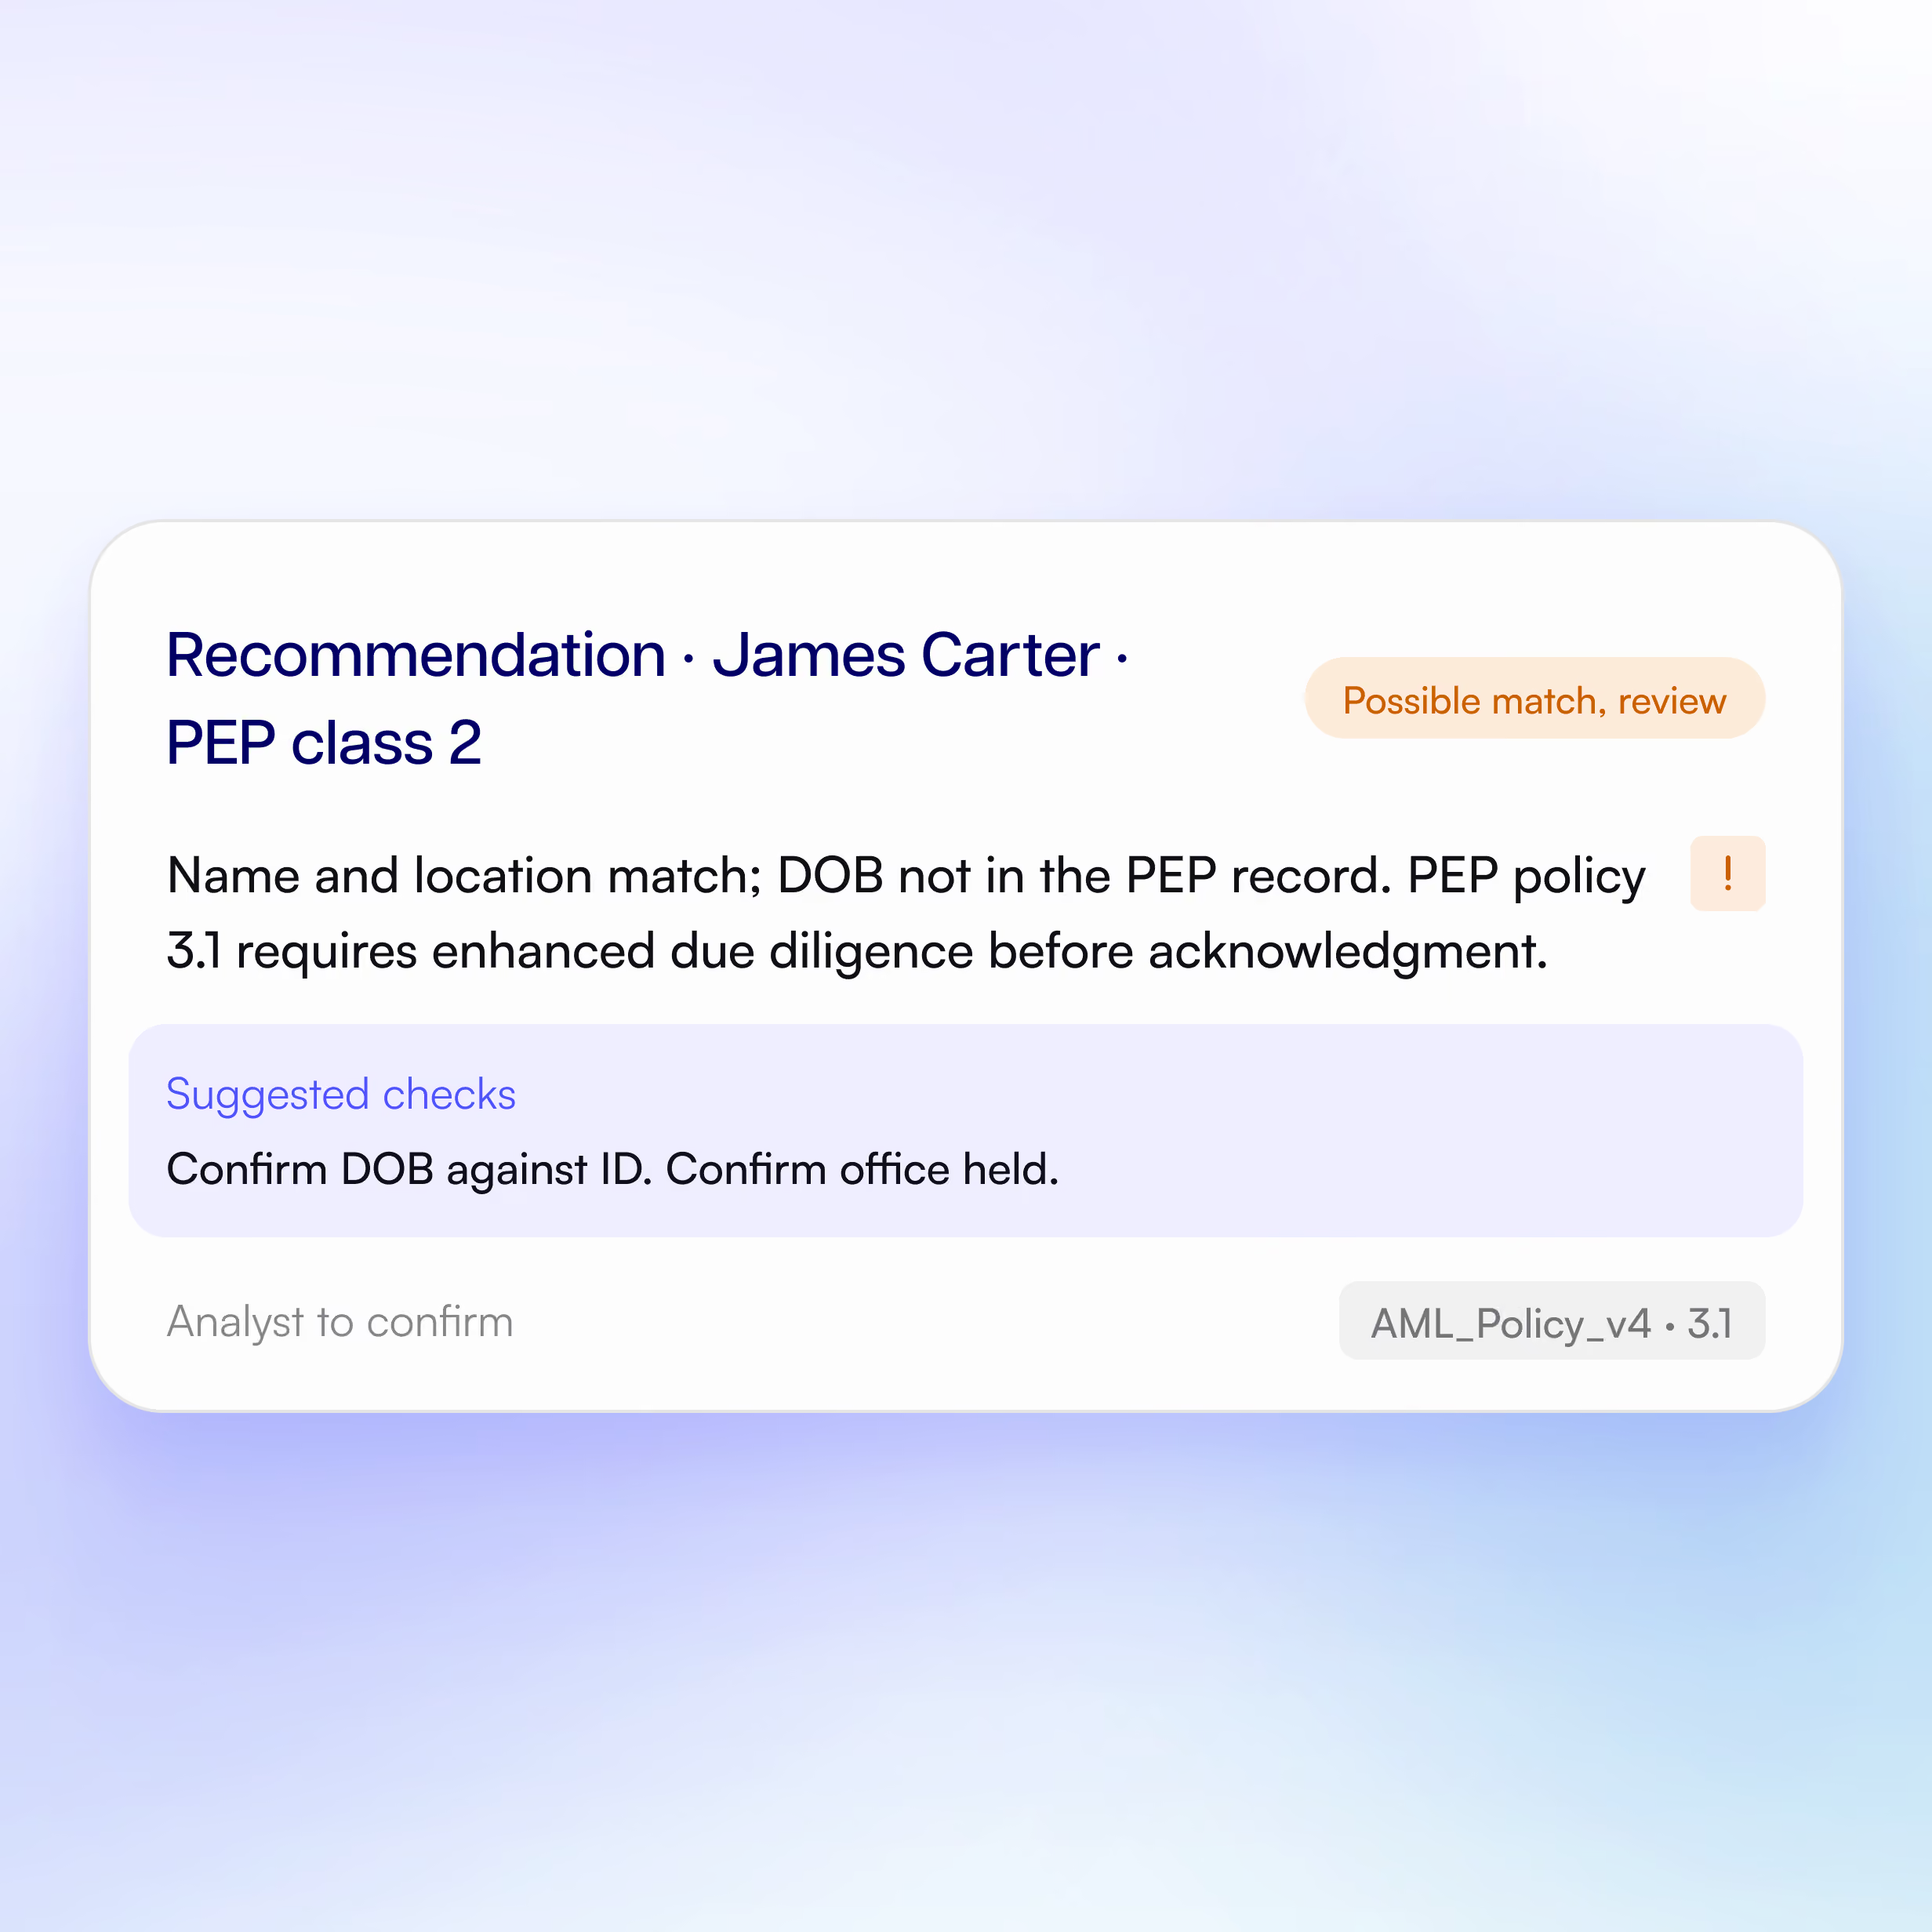
Every recommendation cites your policy
Each rationale names the clause it relied on, so every disposition is already explained for audits or senior stakeholders.
Your AML policy, read by the agent
Upload your policy, choose your lists, set the name match. Every hit is read against it, so case one and case four hundred get the same call.
The agent recommends. Your analyst decides
Three possible recommendations, each with a written rationale. Nothing is cleared or declined until an analyst says so.
Every recommendation cites your policy
Each rationale names the clause it relied on, so every disposition is already explained for audits or senior stakeholders.
Your AML policy, read by the agent
Upload your policy, choose your lists, set the name match. Every hit is read against it, so case one and case four hundred get the same call.
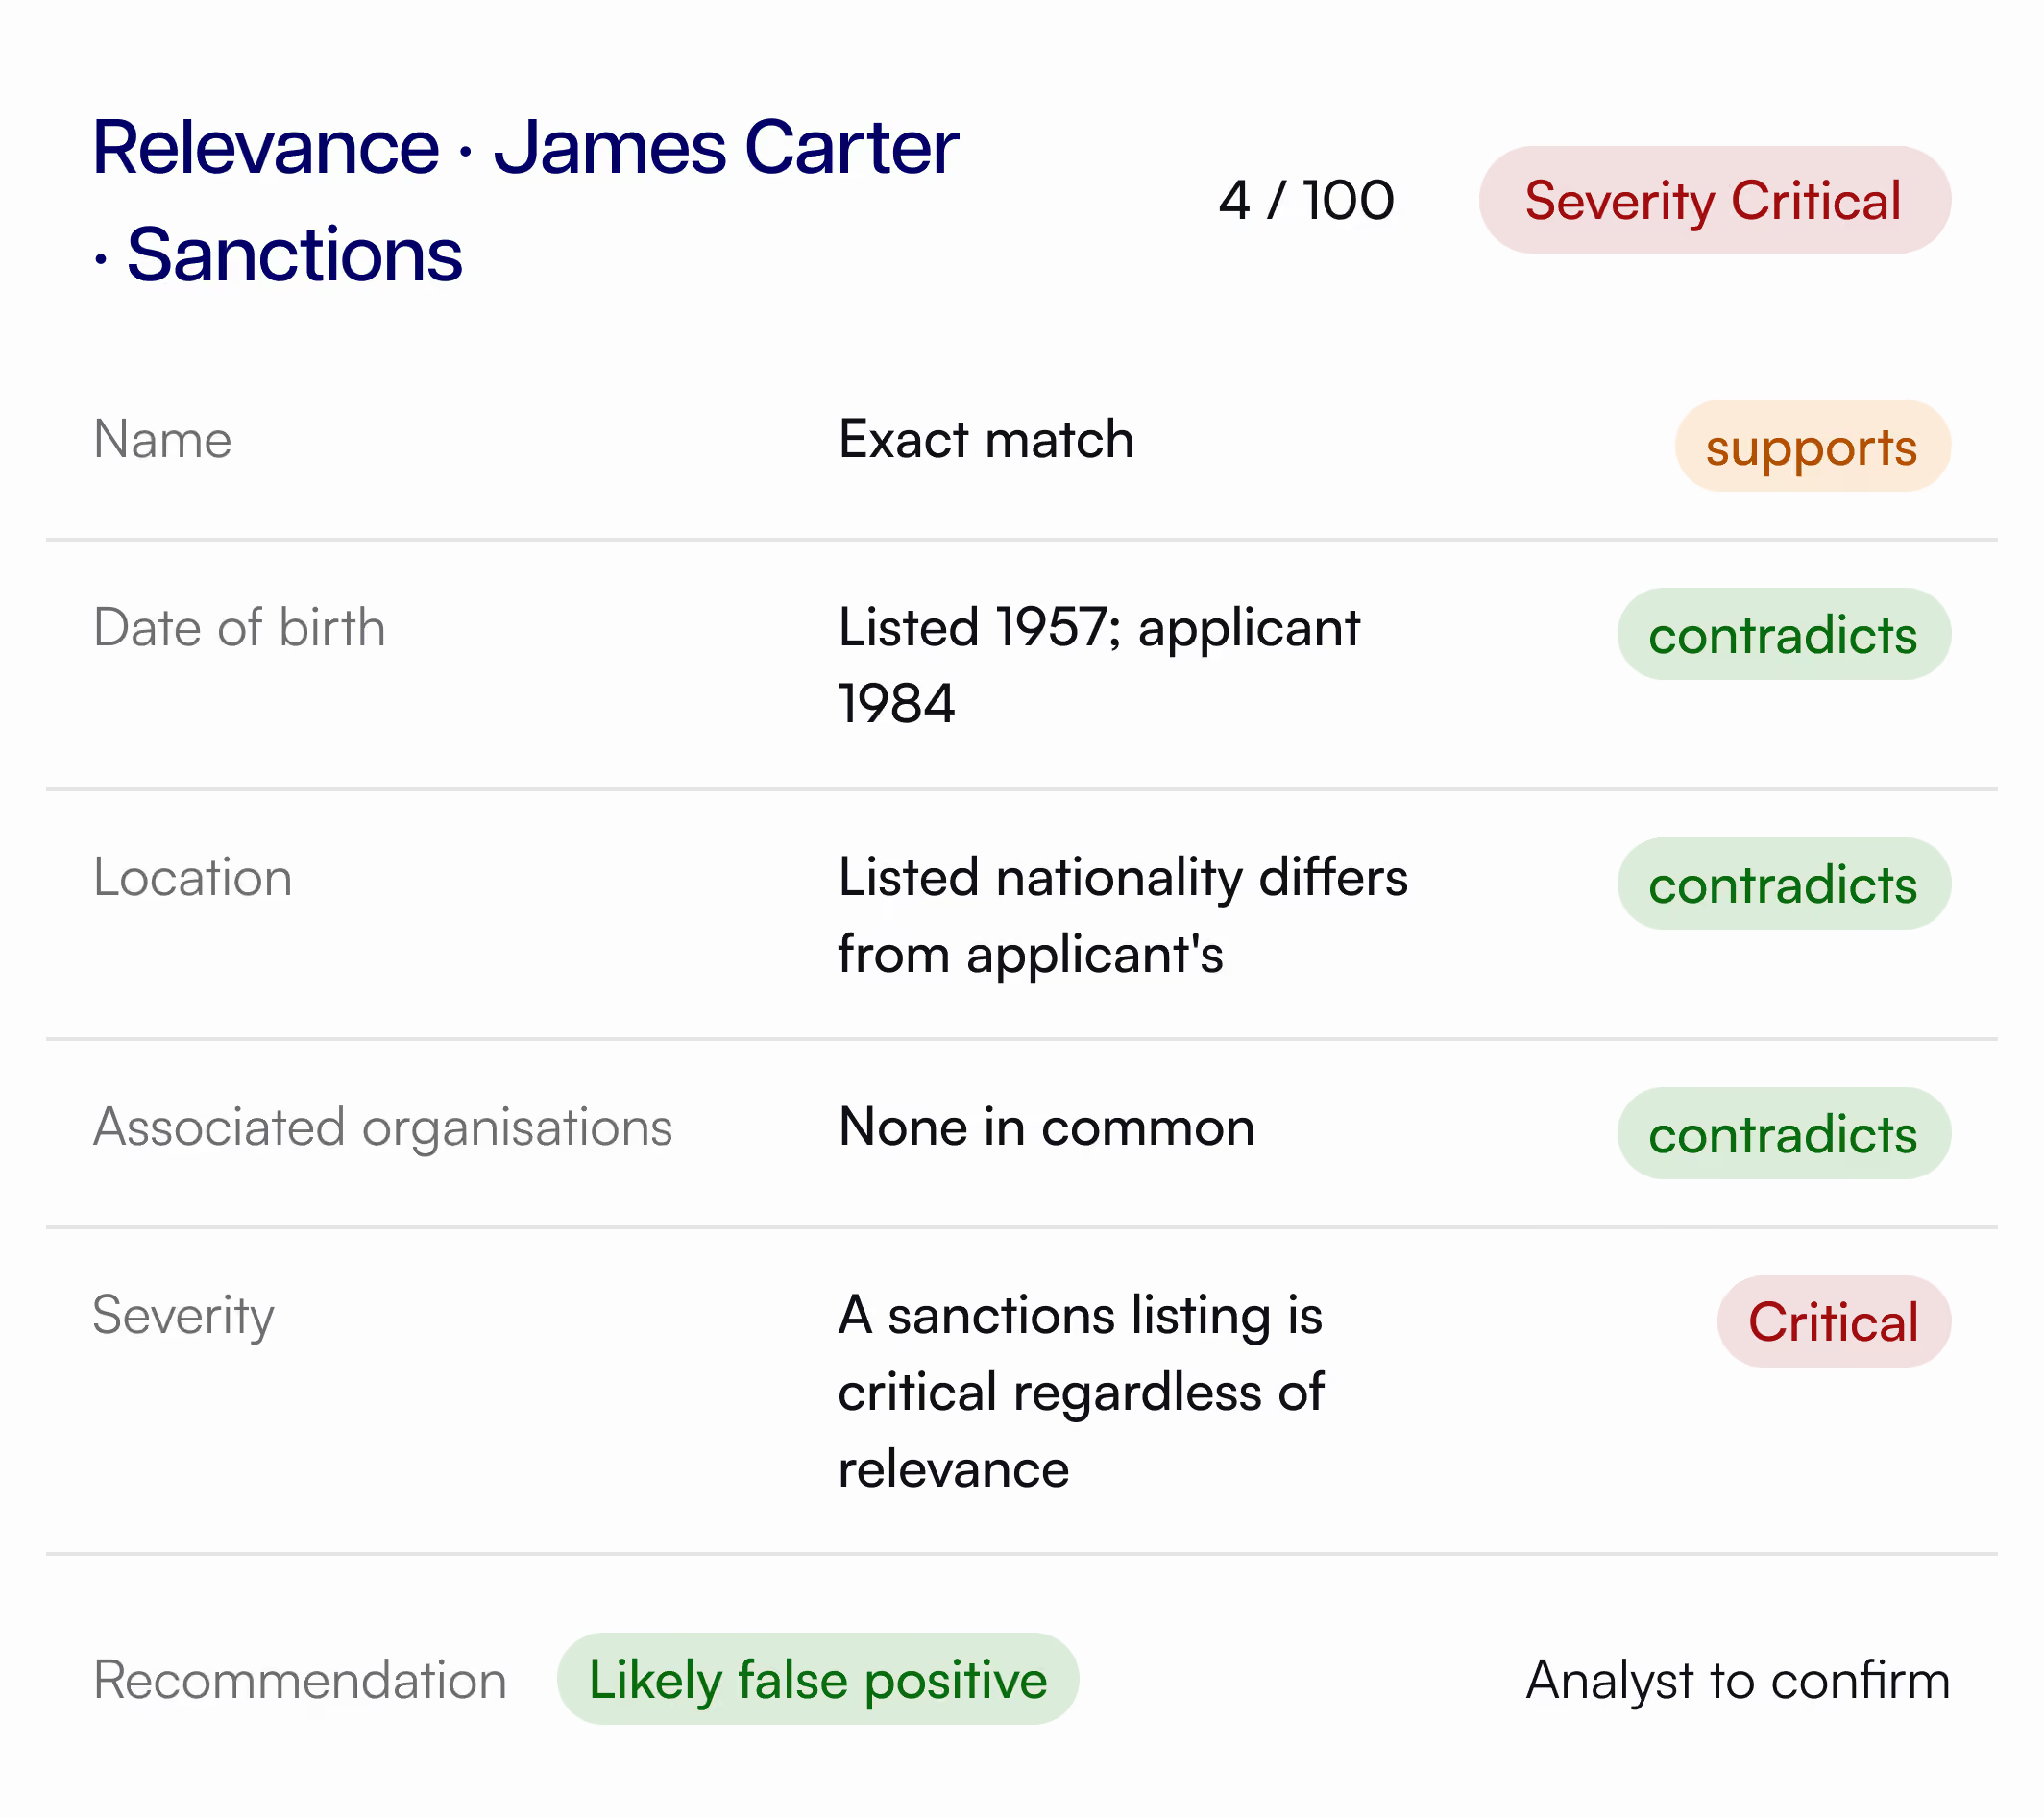
Same nameis not the same person
Screening matches strings. The agent matches people. It compares name variants, age, location, and associated organisations, then scores identity and severity separately.
Low relevance, critical severity: false positive to confirm. High relevance, low severity: a real person doing nothing wrong. High and high: where analyst time belongs.

When the lists change, the agent reads again
When a monitored entity picks up a new hit, the agent re-reads it and shows your analyst what changed. Confirmed false positives stay cleared and stop being monitored.
What teamsget back
Based on customer-reported outcomes. Results vary by program configuration and policy.
saved per AML hit
from hit to risk decision
monitoring after onboarding
audit trail on every decision
Frequently asked questions
More of the review, handled
Document Agent
Reads and cross-checks documents against your policy.
Website Agent
Reviews a business's website and online footprint, returns a decision.
Athena Agent
Reviews the full business profile and recommends a decision.
Sherlock Agent
Investigates KYC fraud across a user's profile, returns CLEAN or FRAUD.